Questory
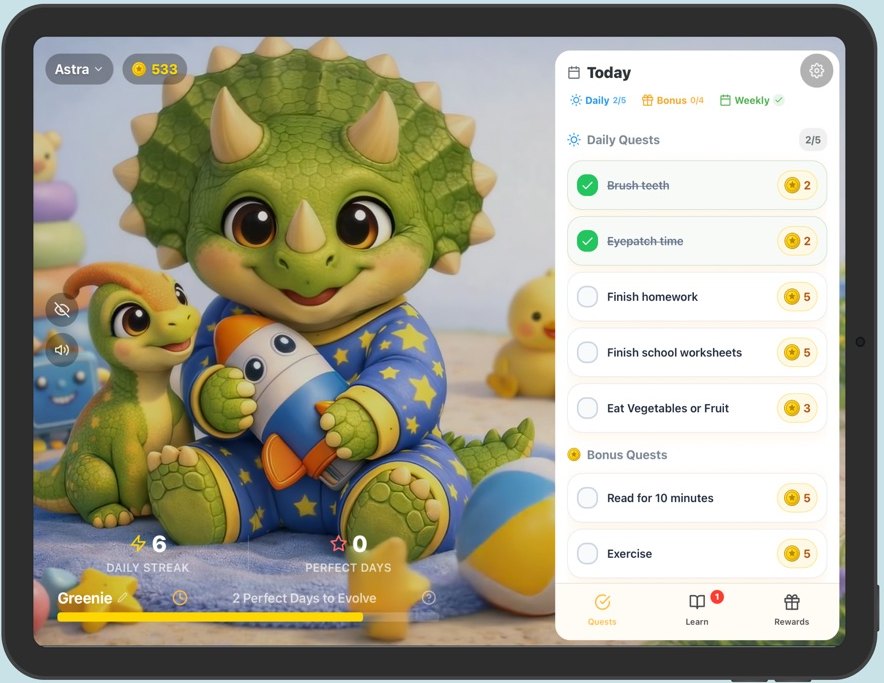
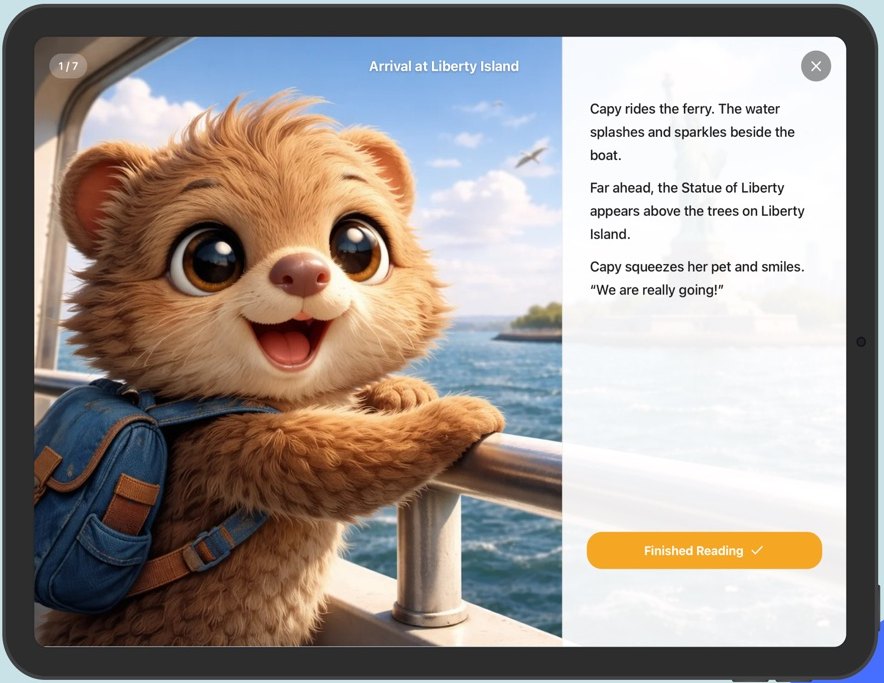
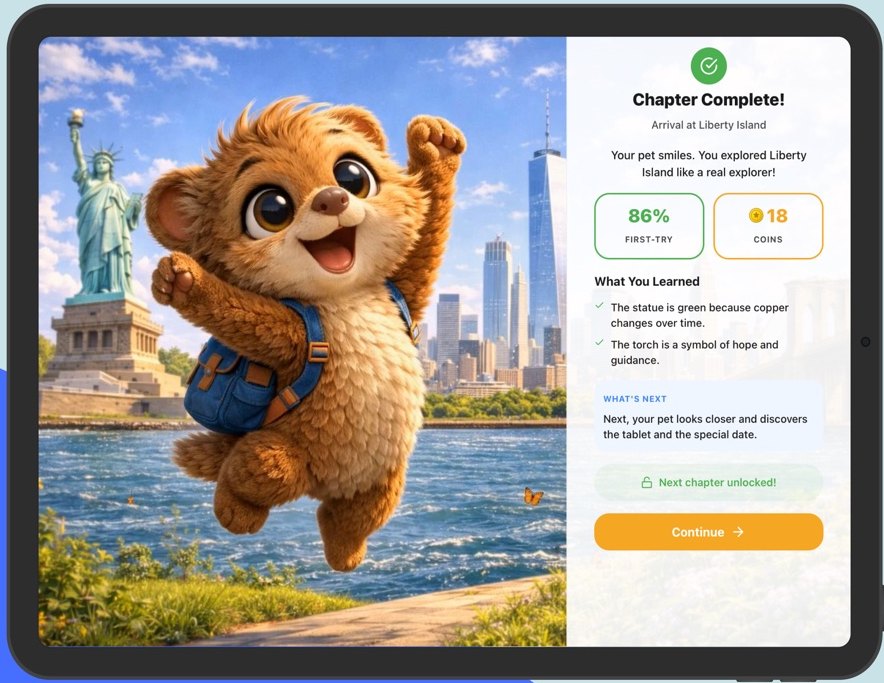
A quest-and-story app for kids: habits, reading and a virtual pet.
Designed and built solo by AJ Pardilla, with AI agents as the engineering team.
- 1,158 commits in 8 weeks
- Privacy label: data not collected
I spent twenty years designing and building products. Now I build the agents that build them with me.
VP of Product and AI, Unicity International
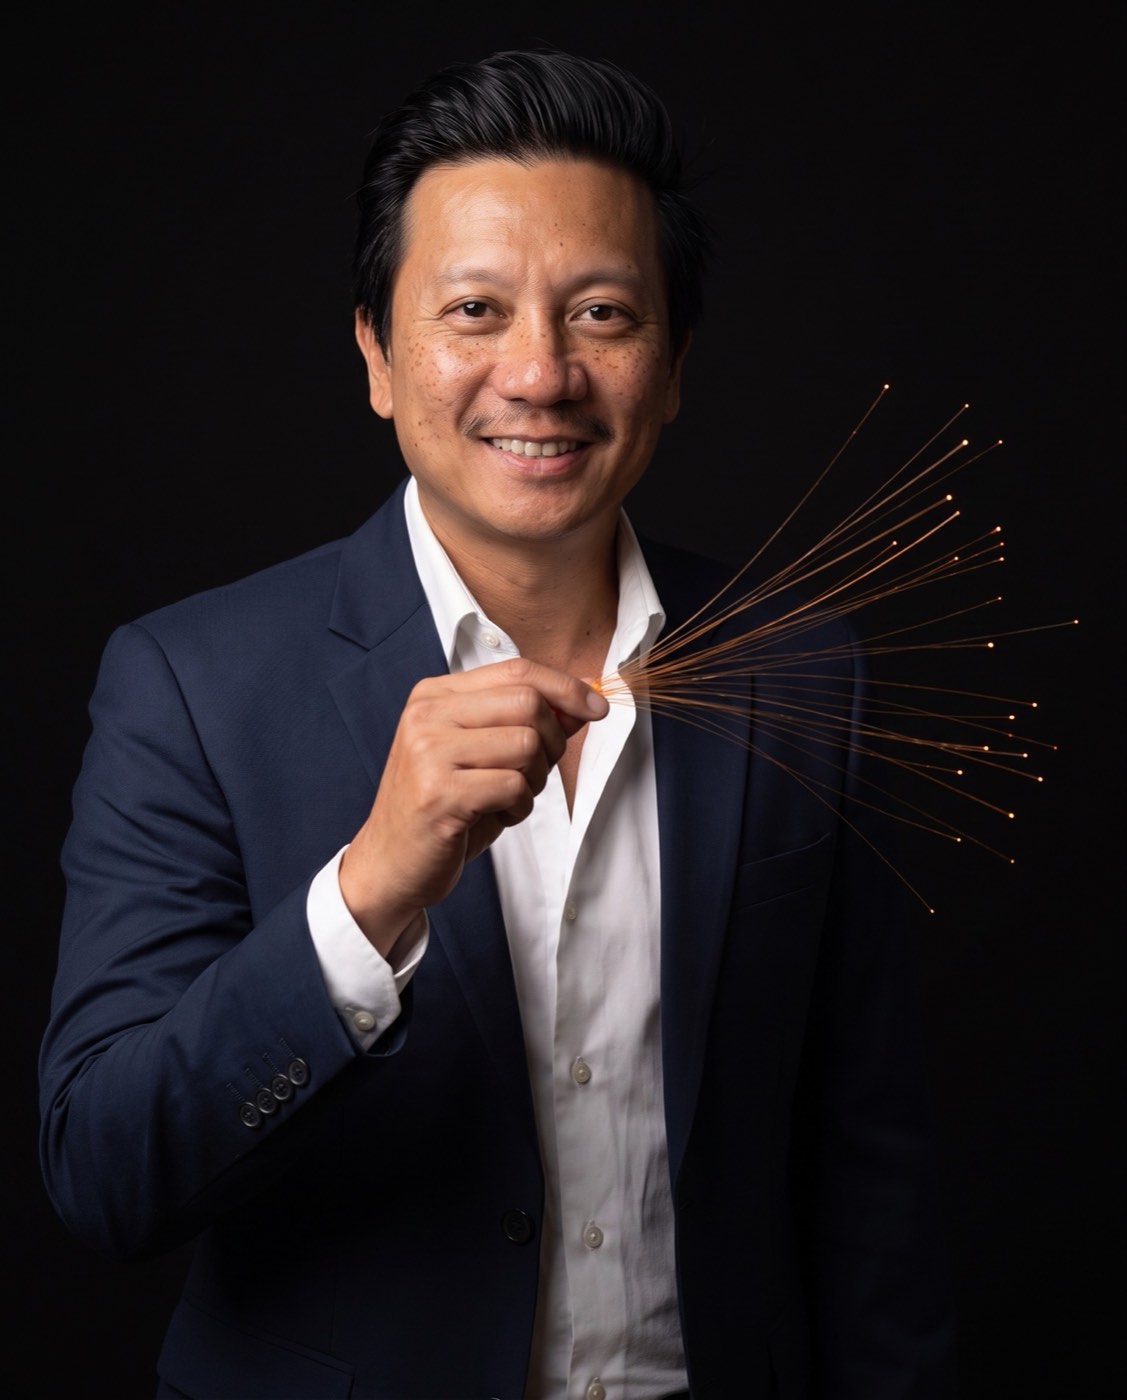
I lead product and AI at Unicity International: 13 direct reports, 8 product teams, and the checkout and payments stack for more than 50 markets. This is my design portfolio. The work on show is the agents I built, with what I taught each one and how I check it.
The register, current at 18 September 2026
76 agents across 12 systems.
30 run on a clock, 33 on command. The other 13 are built and waiting for command.
12 systems, ordered by what actually runs. Open one to meet its agents
55 of these were read out of the files on my own machine. 21 are Grok bots, seen running in my workspace on 18 September 2026 and not audited past that. Each entry says which.
The method comes with me. Agents built inside a company stay there, and get rebuilt inside the next one under its rules.
76 of 76 shown
No agent matches that. Clear the field, or choose All.
16 agents, 16 running
A sixteen-role software team for a mobile app: research, plan, design, build, test, review, release.
The 3 receipts in this system come from one run on 21 August 2026, not 3 separate ones. Some stages passed only after I overrode a failing grade.
Never invent metrics or claim a launch proved success by itself.Do not fabricate data, declare KPI impact from release alone, query protected data without authority, write providers, approve work, or create agents.
The dispatcher can't change anything in a live system, approve work, or leak its thinking.Do not perform provider writes, approve a handoff, or expose private reasoning.
It designs database changes but is never allowed to run them live.Do not apply a migration, change live data, use production credentials, approve the candidate, or create agents.
Never touch or influence the independent QA checking your own design.Do not act as, select, prompt, dismiss, or edit the findings of Independent UX QA.
Never grade your own code or rewrite the rules to pass.Do not approve your own work, change acceptance criteria, or create other agents.
One serious problem can't be smoothed over by a good average score.Do not average away a veto, override a hard gate, or approve merge, data, build, submit, or release.
Never make up a translation and pass it off as translator-approved.Do not invent translator-approved copy, overwrite shared translation sources, write providers, approve work, or create agents.
A clean review must prove it actually looked, not just say fine.Limit ordinary findings to five, deduplicate them, and make zero-finding reviews falsifiable.
Every applicable screen state needs its own real screenshot, not a generic stand-in.Do not approve your own work or substitute generic screenshots for state coverage.
Never claim a device test ran when it didn't, and never relax the QA bar.Do not lower mobile QA, claim unrun device evidence, write providers, approve work, or create agents.
Unresolved product decisions have to surface, not get buried in engineering tasks.Do not hide unresolved product decisions inside engineering instructions.
A generic 'it loads' test doesn't count as real coverage.Do not substitute a generic smoke test for task-specific acceptance coverage.
A good score, a passed QA run or a deadline never adds up to permission to build a release.Do not infer build authority from submit authority, QA, a rubric score, or urgency.
Research informs the decision; it never makes the decision up.Do not select the product decision, write the canonical plan, or fabricate market evidence.
It flags security risks but never touches real secrets or live systems.Do not handle production secrets, weaken controls, run destructive tests, write providers, approve a release, or create agents.
16 agents, 15 running
Gathers signals from Slack, ClickUp, mail and calendar, writes the morning brief, then reviews itself.
When people disagree, report both positions and who is deciding, never a winner.Never silently pick one side.
Don't make a solved problem sound like it's still open.Resolved means resolved. Never present a resolved item as pending.
9 agents, 9 running
Takes one feature or bug from research to a graded, tested, committed change.
The 9 receipts in this system come from one run on 6 September 2026, not 9 separate ones. Some stages passed only after I overrode a failing grade.
Score the actual output, not how hard it tried.Grade the artifact, not the effort.
Prove the test fails first, then write the fix.Never write implementation code before its failing test exists.
Do not fake agreement between the two reviewing models; dissent is preserved word for word.Never manufacture consensus.
Do not add filler requirements just to look complete.Never pad the criteria list to look thorough; each one must earn its place.
Do not claim a test proves something it does not check.Never mark a criterion covered when the test does not actually assert it.
Do not invent problems for show, and do not shrink a real one to let the work through.Never manufacture findings to look rigorous, and never downgrade a real one to unblock the gate.
8 agents, 8 running
Eight bots argue a trade. Risk can veto it, and no order is placed without AJ.
5 agents, 5 running
Finds evidence, reports what people actually said, and grades its own packets.
4 agents, 4 running
Chief of staff, critic, coach, and the chair of the trading desk.
4 agents, 4 running
The work lane: weekday brief, HR drafts, brand, and build.
1 agent, 1 running
Checks each morning that the AI department's own reporting actually ran.
1 agent, 1 running
Answers employees' HR policy questions in Slack with a source on every answer.
5 agents, 0 running
Reads changes to a global storefront before they are allowed near a pull request.
Wrongly approving bad work is the worst outcome; failing a borderline change is cheaper.A false PASS is the worst possible outcome
When unsure, stop and ask instead of guessing.If you're unsure about the fix, STOP and ask rather than guessing
4 agents, 0 running
Turns a one-line idea into sourced evidence, a critic's attack, and a go or no-go.
Stopping a bad idea early counts as the process working.A killed idea early is a success for this process, not a failure.
Only label something 'verified' if it was actually checked.Never move something into "working now (verified)" that no one has verified.
Every fact and figure must be real, never made up.Never invent a number, a baseline, a competitor, or a product feature.
3 agents, 0 running
Pulls app analytics and feedback, ranks what to build next, and builds one.
4 of 11 are enforced by code
Never run a database write without the human explicitly approving that exact change first.
Enforced by a hook that stops the call and makes the human approve itKeep personal and work identities separate on every service; a guard blocks the wrong one automatically.
Enforced by a hook that blocks the actionAlways set the model explicitly per agent call; the strongest model is reserved for the hardest judgment seats.
Enforced by a hook that blocks the actionScore outbound writing on five clarity dimensions and revise anything below the pass threshold before sending.
Enforced by a hook that fires before every outbound send and forces the checkStress-test ideas and lead with what's wrong before offering any praise.
A rule I followExplain work in plain terms and sort progress into working, unproven, and dependent-on-others, honestly.
A rule I followNever start the multi-agent pipeline on an ordinary request; recommend it and wait for explicit approval.
A rule I followRun an adversarial Claude-versus-Codex debate on a plan and resolve blockers before building starts.
A rule I followWrite the failing test before writing the fix, and never edit a test just to make it pass.
A rule I followNever install internal tooling, tracking, or process into a third-party repo without explicit case-by-case approval.
A rule I followNever let two agents edit the same repository at once unless they touch completely separate files.
A rule I followLive in the stores
A quest-and-story app for kids: habits, reading and a virtual pet.
Designed and built solo by AJ Pardilla, with AI agents as the engineering team.
The daily-practice companion for graduates of The Method Seminar: goals, vision, breathwork and streaks, in nine languages.
Designed and built solo by AJ Pardilla, with AI agents as the engineering team. Published by Unicity.
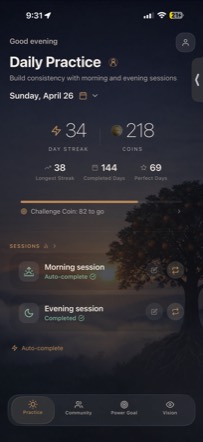
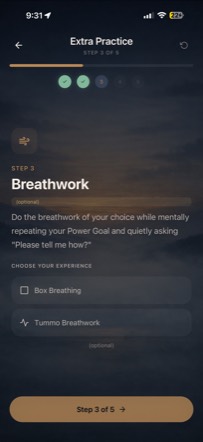
In the week of 31 August 2026: 808 people used The Method, 466 a day, 517 of them practised, 4,726 sessions.
58% of weekly users open the app on any given day. Average daily users grew from 75 in April to 475 in September, with a peak of 493 on 9 August.
New members still practising, by day
Not there yet
The Method Weekly Pulse, production analytics in Mixpanel, project 4001739, generated 11 September 2026. Small internal and testing traffic may be included.
Eight steps, and where each one really runs
Cloud agents that take a feature from a Slack message to a reviewed, device-tested build AJ approves from his phone. About ten dollars a month.
Between 5 and 13 September 2026, three Slack requests were planned, coded and independently reviewed by agents in the cloud. One came back as a build AJ approved from his phone, and the cloud recorded that approval and advanced the ticket by itself.
30 agents in the register run on a clock and need nobody. This pipeline cannot yet: two of its eight steps wait on me.
Sixteen agent roles are defined and eight have run. Running with the computer shut is not proven, and nothing from this pipeline has merged into the app yet.
Five, each with the thing you would check
56 pieces. 10 can be opened from here, and those come first
56 of 56 shown
In order
Nutrigold. Studies Weekly. Ridgway. Unicity International.
Unicity International, 2022 to now
| Checkout approval, EU and Japan | 64% | to | 94% |
|---|---|---|---|
| Product launches per year, counted by market | 3 | to | 40 |
| Fraud rate on those checkouts | about 30% | to | under 1% |
These three are from my own record of the work.
Elsewhere
Father to Astra. Husband to Mariko.
About ten countries a year. Space and technology are the two subjects I never get tired of reading about.
By the agents it describes
I directed agents to build this page. One set swept my machine and my Grok workspace and listed every agent it could find. A second set audited the first, opened the files behind each claim, and cut my own headline from "hundreds" to the 76 on this page.
Four designs were then built from the same audited file, and three judges scored them. This page is the merge they asked for. Every number on it is computed from the audited file when the page is built, so it cannot drift from the data.
If any of this is useful to you, or you think one of these numbers is wrong, I would like to hear it.
Every number on this page was counted from the audited file when the page was built. 76 agents in the register, 63 of them running.
Start a conversationRegister current at 18 September 2026
On LinkedIn